GPU instances for AI inference
Run your own model-serving stack on GPU containers, VMs, or bare metal across Fluence’s decentralized GPU marketplace. Choose your GPU, region, and provider with transparent pricing and zero egress fees.


GPU
H200

Fluence
$2.56/hr

CoreWeave
$6.30/hr

AWS
$7.90/hr

Google Cloud
$10.84/hr

GPU instances for AI inference
Run your own model-serving stack on GPU containers, VMs, or bare metal across Fluence’s decentralized GPU marketplace. Choose your GPU, region, and provider with transparent pricing and zero egress fees.
GPU
H200
Fluence
$2.56/hr
CoreWeave
$6.30/hr
AWS
$7.90/hr
Google Cloud
$10.84/hr
Available GPUs for AI inference
All
Container
VM
Bare Metal
Available GPUs for AI inference
All
Container
VM
Bare Metal
Choose how you want to run inference


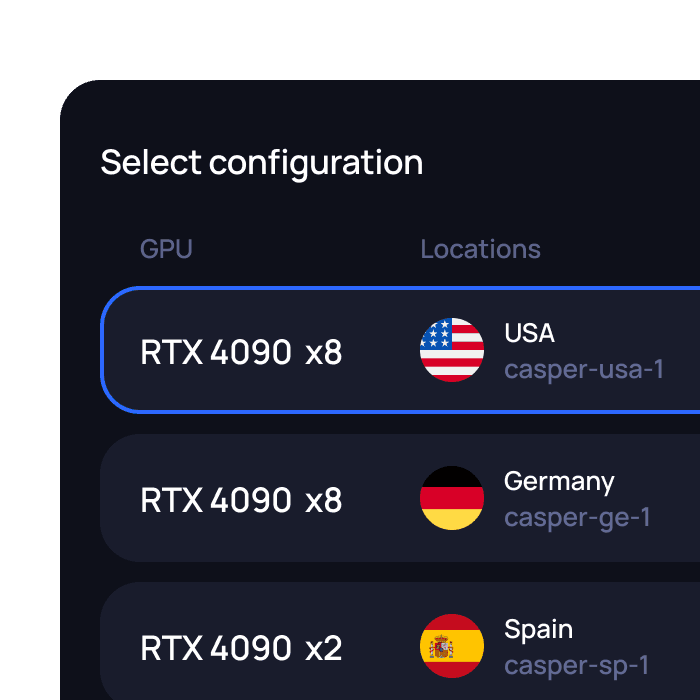
Choose how you want to run inference
What you can run on Fluence AI compute
What you can run on Fluence AI compute
Why choose Fluence for AI inference
Why choose Fluence for AI inference
Request a custom GPU cluster
Need a different GPU setup or configuration? Send us your requirements and our team will get back to you.
Request a custom GPU cluster
Need a different GPU setup or configuration? Send us your requirements and our team will get back to you.
Top-tier hardware at best-in-class locations
Certified for compliance with GDPR, SOC2, and ISO 27001 standards. Tier-3 and Tier-4 data centers with high availability, enterprise-grade performant servers.
Top-tier hardware at best-in-class locations
Certified for compliance with GDPR, SOC2, and ISO 27001 standards. Tier-3 and Tier-4 data centers with high availability, enterprise-grade performant servers.
FAQ
What is Fluence AI
Is Fluence AI only for GPU workloads
What can I run on GPU Cloud
What can I run on Virtual Servers
How do GPU Cloud and Virtual Servers work together
Show more
FAQ
What is Fluence AI
Is Fluence AI only for GPU workloads
What can I run on GPU Cloud
What can I run on Virtual Servers
How do GPU Cloud and Virtual Servers work together
Show more

Be the first to know


Be the first to know