GPU instances for AI model Fine-tuning
Fine-tune large language models, vision models, and generative AI models with LoRA, QLoRA, supervised fine-tuning, or full-parameter training. Choose GPU containers, VMs, or bare metal with transparent hourly pricing and zero egress fees.


GPU
H200

Fluence
$2.56/hr

CoreWeave
$6.30/hr

AWS
$7.90/hr

Google Cloud
$10.84/hr

GPU instances for AI model Fine-tuning
Fine-tune large language models, vision models, and generative AI models with LoRA, QLoRA, supervised fine-tuning, or full-parameter training. Choose GPU containers, VMs, or bare metal with transparent hourly pricing and zero egress fees.
GPU
H200
Fluence
$2.56/hr
CoreWeave
$6.30/hr
AWS
$7.90/hr
Google Cloud
$10.84/hr
Available GPUs for AI inference
Choose cloud GPU instances by model, VRAM, deployment type, provider, region, and hourly price. Find the configuration that fits your fine-tuning method, model size, and expected runtime.
All
Container
VM
Bare Metal
H200
141 GB
Info
141 GB RAM
Deployment
Container
Best fit
Memory-heavy fine-tuning
Price
$2.56 /per hr
H100
640 GB
Info
80 GB RAM
Deployment
Bare Metal
Best fit
Multi-GPU fine-tuning
Price
$19.35 /per hr
Choose how you want to fine-tune AI models


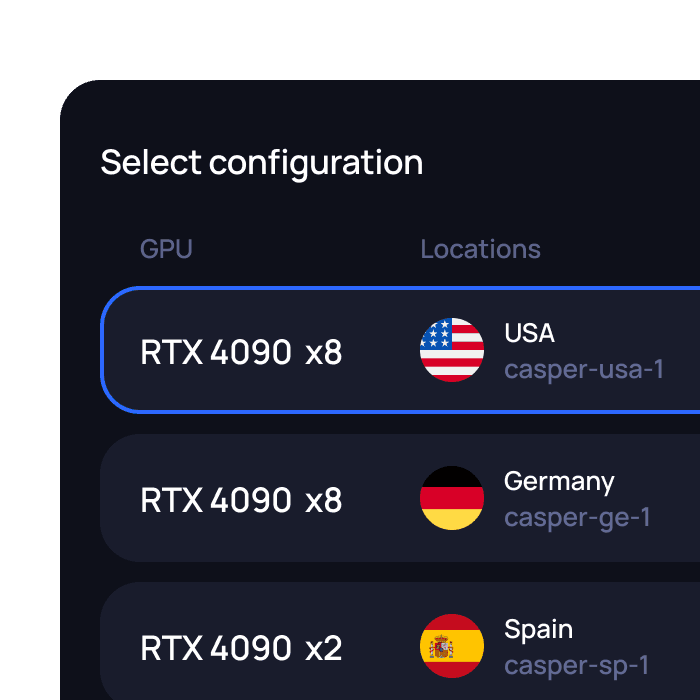
Choose how you want to fine-tune AI models
What you can run on Fluence AI compute
What you can run on Fluence AI compute
Why choose Fluence for LLM fine-tuning
Why choose Fluence for LLM fine-tuning
Request a custom GPU cluster
Need a different GPU setup or configuration? Send us your requirements and our team will get back to you.
Request a custom GPU cluster
Need a different GPU setup or configuration? Send us your requirements and our team will get back to you.
Top-tier GPU infrastructure for AI model fine-tuning
Run LLM and generative AI fine-tuning on high-performance GPU hardware at best-in-class locations. Review the provider, region, hardware configuration, and available compliance information before deployment.
Top-tier GPU infrastructure for AI model fine-tuning
Run LLM and generative AI fine-tuning on high-performance GPU hardware at best-in-class locations. Review the provider, region, hardware configuration, and available compliance information before deployment.
FAQ
What is LLM fine-tuning?
What is the difference between LoRA, QLoRA, and full fine-tuning?
Which GPU is best for LLM fine-tuning?
How much VRAM do I need for LLM fine-tuning?
How much does LLM fine-tuning cost?
Show more
FAQ
What is LLM fine-tuning?
What is the difference between LoRA, QLoRA, and full fine-tuning?
Which GPU is best for LLM fine-tuning?
How much VRAM do I need for LLM fine-tuning?
How much does LLM fine-tuning cost?
Show more

Be the first to know


Be the first to know