
A Hyperstack alternative for more GPU deployment options
Compare Fluence and Hyperstack on GPU costs, provider choice, deployment options, managed services, and the resources your training and inference workloads require.
A Hyperstack alternative for more GPU deployment options
Compare Fluence and Hyperstack on GPU costs, provider choice, deployment options, managed services, and the resources your training and inference workloads require.

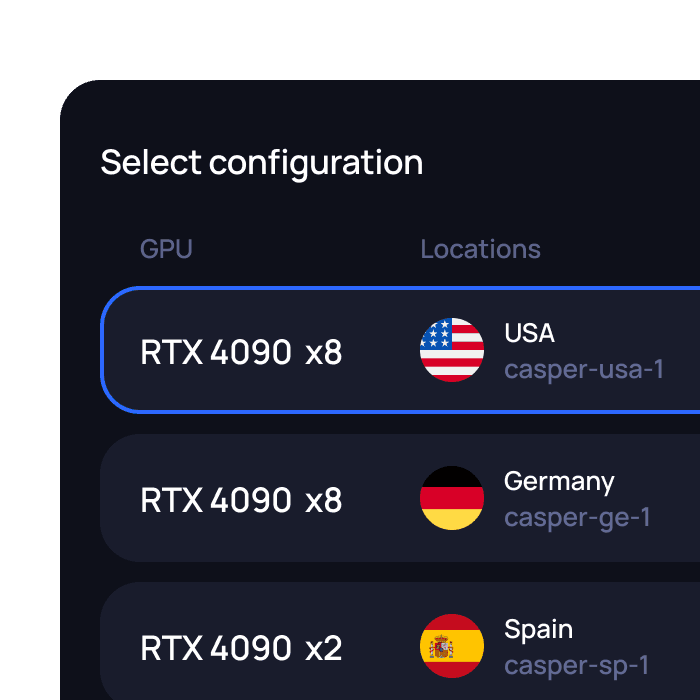
Compare GPU configurations across multiple providers and regions
Run containers, VMs, or bare metal through one console
Keep data transfer predictable with unlimited bandwidth and zero egress fees
Compare GPU configurations across multiple providers and regions
Run containers, VMs, or bare metal through one console
Keep data transfer predictable with unlimited bandwidth and zero egress fees
Fluence vs Hyperstack at a glance
Category
Fluence
Hyperstack
Best for
Provider and deployment choice
GPU VMs and managed AI services
Core experience
Multi-provider GPU cloud
Integrated VM and cluster management
Deployment options
Containers, VMs, bare metal
GPU VMs, Kubernetes, dedicated inference
Provider model
Multiple infrastructure providers
Hyperstack regional cloud
Platform tooling
Console, API, preset or custom images
Console, API, Terraform, snapshots
Cost model
Hourly rates with zero egress fees
On-demand, spot, and reserved rates; zero egress
Fluence vs Hyperstack at a glance
Fluence
Hyperstack
Best for
Provider and deployment choice
GPU VMs and managed AI services
Core experience
Multi-provider GPU cloud
Integrated VM and cluster management
Deployment options
Containers, VMs, bare metal
GPU VMs, Kubernetes, dedicated inference
Provider model
Multiple infrastructure providers
Hyperstack regional cloud
Platform tooling
Console, API, preset or custom images
Console, API, Terraform, snapshots
Cost model
Hourly rates with zero egress fees
On-demand, spot, and reserved rates; zero egress
Compare the full cost of GPU compute
Hyperstack bundles CPU, RAM, and local storage with GPU VMs. Public IPs and shared storage cost extra. Fluence configurations vary by provider. Compare GPU specifications, runtime, storage, and support to estimate total costs. Need another GPU model or configuration? Share your requirements and our team will get back to you.
Compare the full cost of GPU compute
Hyperstack bundles CPU, RAM, and local storage with GPU VMs. Public IPs and shared storage cost extra. Fluence configurations vary by provider. Compare GPU specifications, runtime, storage, and support to estimate total costs. Need another GPU model or configuration? Share your requirements and our team will get back to you.
Choose how your GPU workloads run

GPU containers
Deploy packaged inference services and batch jobs without maintaining a full operating system.

GPU VMs
Configure the operating system, services, and drivers required by your AI stack.
GPU bare metal
Use dedicated physical servers when isolation and direct hardware access are essential.
Choose how your GPU workloads run
GPU containers
Deploy packaged inference services and batch jobs without maintaining a full operating system.
GPU VMs
Configure the operating system, services, and drivers required by your AI stack.
GPU bare metal
Use dedicated physical servers when isolation and direct hardware access are essential.
More choice across your GPU stack
Choose who supplies your GPUs
Compare offers from different infrastructure providers by region, hardware configuration, and price.
Select the deployment format
Launch containers, VMs, or bare metal with the access and isolation your application requires.
Size compute around the workload
Compare GPU count, VRAM, CPU, and storage together to avoid paying for resources you do not need.
Built for AI workloads you manage
Run your preferred stack.
Production inference
Serve models with control over batching, runtime configuration, network access, and GPU allocation.
GPU container or GPU VM
Fine-tuning pipelines
Run adapters, checkpoints, and custom training cycles with your preferred frameworks and storage.
GPU VM or GPU bare metal
LLM development
Evaluate open models, quantization settings, and inference engines in a reproducible environment.
GPU container or GPU VM
Training runs
Run sustained single-server or multi-GPU jobs with control over dependencies, storage, and hardware access.
GPU VM or GPU bare metal
Batch inference
Generate embeddings and process datasets, documents, or media in repeatable GPU batches.
GPU container
Model research
Compare architectures, context lengths, and precision formats while keeping experiment environments consistent.
GPU container or GPU VM
AI agent inference
Self-host the models behind AI agents while retaining control over application services and data.
GPU container or GPU VM
Compare platforms with one GPU workload
Test one workload from your Hyperstack environment before making a broader move. Measure the complete deployment: performance, setup effort, and ongoing cost.

1
Choose a workload
2
Match GPU and memory requirements
3
Select a provider and deployment type
4
Run under expected production load
5
Compare performance and total cost
Compare platforms with one GPU workload
Test one workload from your Hyperstack environment before making a broader move. Measure the complete deployment: performance, setup effort, and ongoing cost.
1
Choose a workload
2
Match GPU and memory requirements
3
Select a provider and deployment type
4
Run under expected production load
5
Compare performance and total cost
FAQ
How do Hyperstack and Fluence differ?
Is Fluence cheaper than Hyperstack?
Which GPUs are available on Hyperstack and Fluence?
Do both platforms support single-GPU and multi-GPU workloads?
How does regional availability compare?
Show more
FAQ
How do Hyperstack and Fluence differ?
Is Fluence cheaper than Hyperstack?
Which GPUs are available on Hyperstack and Fluence?
Do both platforms support single-GPU and multi-GPU workloads?
How does regional availability compare?
Show more

Choose how your next GPU workload runs
Compare providers, configurations, and deployment options, then launch the GPU resources your application needs.