
A Runpod alternative at 80% lower cost
Compare Fluence and Runpod on GPU pricing, deployment control, provider flexibility, billing predictability, networking assumptions, and workload setup across containers, VMs, and bare metal.
A Runpod alternative at 80% lower cost
Compare Fluence and Runpod on GPU pricing, deployment control, provider flexibility, billing predictability, networking assumptions, and workload setup across containers, VMs, and bare metal.

Fluence vs Runpod at a glance
Category
Fluence
Runpod
Main use case
Infrastructure-led GPU workloads
Fast GPU starts, Pods, Serverless, and developer workflows
Core experience
Direct GPU infrastructure access
Managed AI cloud experience
Deployment options
Containers, VMs, bare metal
GPU Pods, Serverless endpoints, clusters
Provider flexibility
Access across multiple providers globally
Runpod platform environment across cloud tiers
Cost model
Predictable hourly pricing with zero egress fees
Fine-grained billing, savings plans, spot, and no Pod ingress/egress fees
Runtime control
Custom images, SSH keys, env vars, forwarded ports, UDP port formats
Templates, custom images, SDKs, CLI, and Serverless scaling
Fluence vs Runpod at a glance
Fluence
Runpod
Main use case
Infrastructure-led GPU workloads
Fast GPU starts, Pods, Serverless, and developer workflows
Core experience
Direct GPU infrastructure access
Managed AI cloud experience
Deployment options
Containers, VMs, bare metal
GPU Pods, Serverless endpoints, clusters
Provider flexibility
Access across multiple providers globally
Runpod platform environment across cloud tiers
Cost model
Predictable hourly pricing with zero egress fees
Fine-grained billing, savings plans, spot, and no Pod ingress/egress fees
Runtime control
Custom images, SSH keys, env vars, forwarded ports, UDP port formats
Templates, custom images, SDKs, CLI, and Serverless scaling
Compare the real cost of GPU compute
GPU pricing can look simple at small scale. It gets harder to manage as workloads run longer and grow across environments. Fluence is designed to give teams a more transparent and predictable GPU cost model.
Compare the real cost of GPU compute
GPU pricing can look simple at small scale. It gets harder to manage as workloads run longer and grow across environments. Fluence is designed to give teams a more transparent and predictable GPU cost model.
Deploy GPU workloads your way


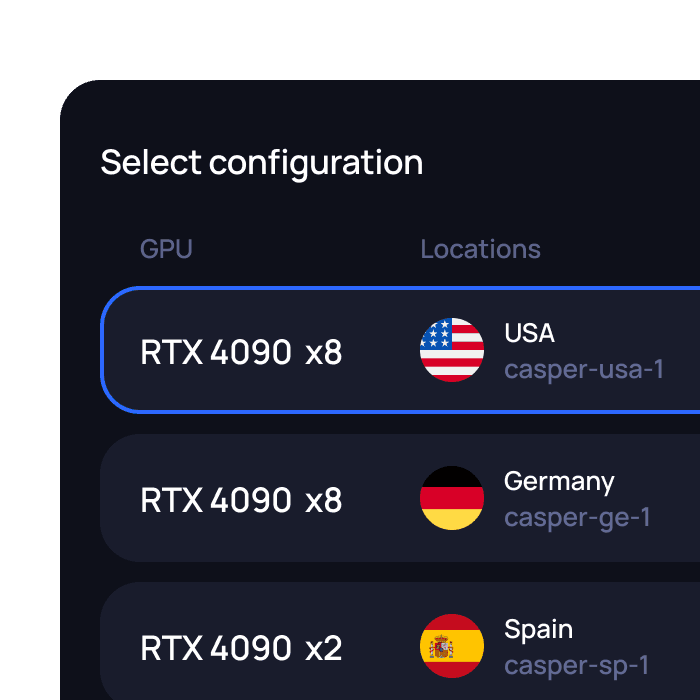
Deploy GPU workloads your way
Where Fluence is different
Where Fluence is different
Built for GPU workloads that need control
Fluence is well suited for:
Built for GPU workloads that need control
Fluence is well suited for:
Test Fluence with one GPU workload
You do not need to replace every Runpod Pod or Serverless endpoint at once. Start with one workload where cost, runtime control, provider placement, or networking behavior matters.

1
Pick a GPU model
2
Choose container, VM, or bare metal
3
Select a region, provider, or available offer
4
Run a small test workload
5
Compare cost, setup experience, and operational control
Test Fluence with one GPU workload
You do not need to replace every Runpod Pod or Serverless endpoint at once. Start with one workload where cost, runtime control, provider placement, or networking behavior matters.
1
Pick a GPU model
2
Choose container, VM, or bare metal
3
Select a region, provider, or available offer
4
Run a small test workload
5
Compare cost, setup experience, and operational control
Frequently Asked Questions (FAQ)
What is the main difference between Runpod and Fluence?
Is Fluence better than Runpod?
Does Fluence support custom Docker images like Runpod?
Is Fluence a Runpod Serverless alternative?
How does billing differ between Runpod and Fluence?
Show more
Frequently Asked Questions (FAQ)
What is the main difference between Runpod and Fluence?
Is Fluence better than Runpod?
Does Fluence support custom Docker images like Runpod?
Is Fluence a Runpod Serverless alternative?
How does billing differ between Runpod and Fluence?
Show more

Move beyond Pods-only GPU workflows
Run GPU workloads with the deployment model, provider placement, and cost structure your team needs as workloads scale.