
A Together AI alternative at 69% lower costs
Compare Fluence and Together AI across GPU pricing, provider choice, deployment control, managed AI services, and infrastructure requirements for training and inference.
A Together AI alternative at 69% lower costs
Compare Fluence and Together AI across GPU pricing, provider choice, deployment control, managed AI services, and infrastructure requirements for training and inference.

Fluence vs Together AI at a glance
Category
Fluence
Together AI
Best for
Self-managed AI workloads and custom infrastructure
Managed inference, fine-tuning, and large GPU clusters
Core experience
Direct infrastructure control across providers
Managed model services and cluster operations
Deployment options
GPU containers, VMs, bare metal
Serverless and dedicated inference, dedicated containers, Kubernetes and Slurm clusters
Provider flexibility
Capacity across multiple providers
Together AI-operated infrastructure
Platform tooling
Console, API, preset or custom images
APIs, CLI, Terraform, SkyPilot, managed orchestration
Cost model
Transparent hourly pricing with zero egress fees
Per-token and per-GPU pricing across on-demand, reserved, and preemptible capacity
Fluence vs Together AI at a glance
Fluence
Together AI
Best for
Self-managed AI workloads and custom infrastructure
Managed inference, fine-tuning, and large GPU clusters
Core experience
Direct infrastructure control across providers
Managed model services and cluster operations
Deployment options
GPU containers, VMs, bare metal
Serverless and dedicated inference, dedicated containers, Kubernetes and Slurm clusters
Provider flexibility
Capacity across multiple providers
Together AI-operated infrastructure
Platform tooling
Console, API, preset or custom images
APIs, CLI, Terraform, SkyPilot, managed orchestration
Cost model
Transparent hourly pricing with zero egress fees
Per-token and per-GPU pricing across on-demand, reserved, and preemptible capacity
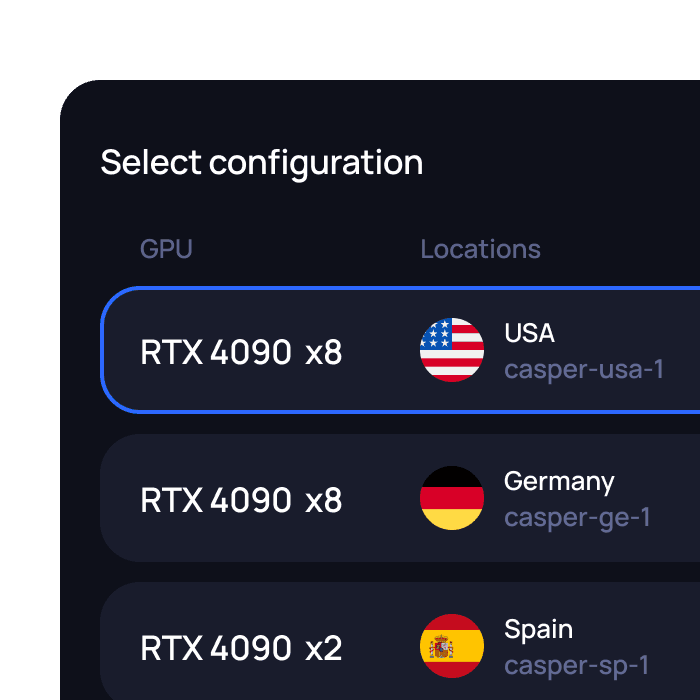
Compare the real cost of GPU compute
Together AI prices serverless inference by token and GPU clusters by GPU-hour. Fluence pricing varies by provider, GPU model, and deployment type. Compare the full configuration, runtime, and managed services to understand the real cost of each option. Need another GPU model or setup? Send us your requirements and we will get back to you.
Compare the real cost of GPU compute
Together AI prices serverless inference by token and GPU clusters by GPU-hour. Fluence pricing varies by provider, GPU model, and deployment type. Compare the full configuration, runtime, and managed services to understand the real cost of each option. Need another GPU model or setup? Send us your requirements and we will get back to you.
Run GPU workloads on your terms


Run GPU workloads on your terms
Where Fluence gives you more control
Where Fluence gives you more control
Built for self-managed GPU workloads
Fluence is well suited for:
Built for self-managed GPU workloads
Fluence is well suited for:
Test Fluence with one GPU workload
Recreate one representative workload and compare cost, setup, performance, and infrastructure control before expanding the deployment.

1
Choose a workload
2
Match its GPU and memory requirements
3
Select container, VM, or bare metal
4
Run under production-like conditions
5
Compare cost, performance, and control
Test Fluence with one GPU workload
Recreate one representative workload and compare cost, setup, performance, and infrastructure control before expanding the deployment.
1
Choose a workload
2
Match its GPU and memory requirements
3
Select container, VM, or bare metal
4
Run under production-like conditions
5
Compare cost, performance, and control
FAQ
How do Together AI and Fluence differ?
How much can Fluence save compared with Together AI?
Which GPUs are available on Together AI and Fluence?
Do both platforms support single-GPU and multi-GPU workloads?
How does regional availability compare?
Show more
FAQ
How do Together AI and Fluence differ?
How much can Fluence save compared with Together AI?
Which GPUs are available on Together AI and Fluence?
Do both platforms support single-GPU and multi-GPU workloads?
How does regional availability compare?
Show more

Run AI workloads on infrastructure you control
Compare GPU offers across providers and choose the deployment model, region, and configuration required by your stack.