A Vast.ai alternative
for predictable GPU costs

Compare Fluence and Vast.ai on GPU pricing, bandwidth costs, provider choice, deployment options, and workload fit across containers, VMs, bare metal, and serverless inference.

Host OpenClaw on always-on Virtual Servers for up to 85% less cost and connect it to external LLM APIs or routing layers. When you need self-hosted inference, you can also pair OpenClaw with Fluence GPU Cloud.

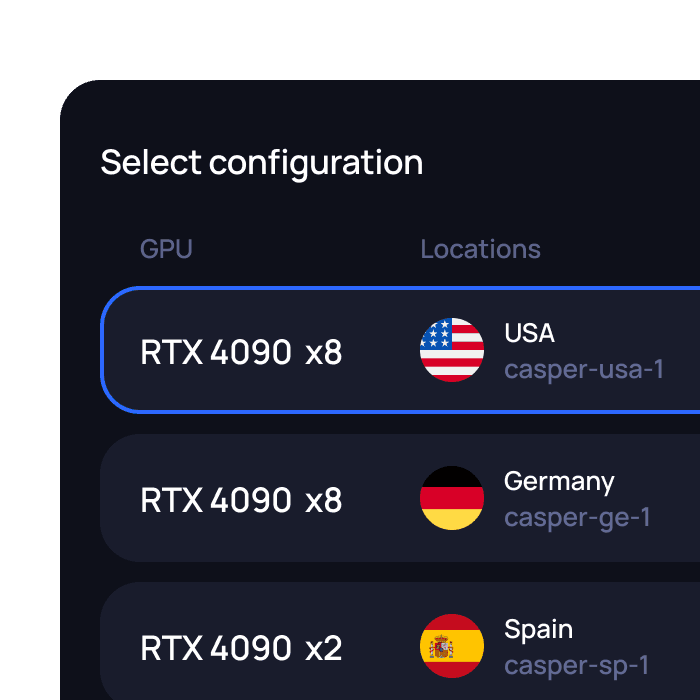
Compare GPU capacity across providers and regions

Compare GPU capacity across providers and regions

Unlimited bandwidth and zero egress fees simplify data-heavy workload costs

Choose containers, virtual machines, or bare metal for each workload

Fluence vs Vast.ai at a glance

Category

Fluence

Vast.ai

Best for

Production workloads with predictable costs

Broad GPU choice and market-driven pricing

Core experience

Provider choice with direct control

Marketplace search with API-native provisioning

Deployment options

Containers, VMs, bare metal

Docker instances, VMs, Serverless, dedicated clusters

Provider flexibility

Offers across infrastructure providers

Community hosts and data centers

Platform tooling

Preset or custom environments, Fluence API

Templates, CLI, SDK, REST API

Cost model

Visible hourly pricing, zero egress fees

Per-second compute plus storage and bandwidth charges

Fluence

Vast.ai

Best for

Production workloads with predictable costs

Broad GPU choice and market-driven pricing

Core experience

Provider choice with direct control

Marketplace search with API-native provisioning

Deployment options

Containers, VMs, bare metal

Docker instances, VMs, Serverless, dedicated clusters

Provider flexibility

Offers across infrastructure providers

Community hosts and data centers

Platform tooling

Preset or custom environments, Fluence API

Templates, CLI, SDK, REST API

Cost model

Visible hourly pricing, zero egress fees

Per-second compute plus storage and bandwidth charges

Compare the real cost
of GPU compute

Compare the real costof GPU compute

Compare the real cost
of GPU compute

Vast.ai prices compute, storage, and bandwidth separately, with host-specific rates. Fluence includes unlimited bandwidth and zero egress fees.


Compare the GPU configuration, expected runtime, storage, and data movement to understand the total cost of each option.


Need another GPU model or configuration? Send us your requirements and our team will get back to you.

Need a different GPU setup or configuration?

Send us your requirements and our team will get back to you.

Need a different GPU setup or configuration?

Send us your requirements and our team will get back to you.

Run GPU workloads your way

GPU Containers

Package repeatable workloads without maintaining a full operating system.

GPU VMs

Use a complete operating system for persistent services and system-level tools.
Bare Metal

Run directly on dedicated servers for maximum hardware control.

Where Fluence is different

Where Fluence is different

Keep data transfer predictable

Keep data transfer predictable

Unlimited bandwidth and zero egress fees simplify planning for datasets, checkpoints, artifacts, and model outputs.

Unlimited bandwidth and zero egress fees simplify planning for datasets, checkpoints, artifacts, and model outputs.

Keep data transfer predictable

Unlimited bandwidth and zero egress fees simplify planning for datasets, checkpoints, artifacts, and model outputs.

Choose the deployment model

Choose the deployment model

Use containers, VMs, or bare metal based on workload control and isolation needs.

Use containers, VMs, or bare metal based on workload control and isolation needs.

Choose the deployment model

Use containers, VMs, or bare metal based on workload control and isolation needs.

Choose the deployment model

Use containers, VMs, or bare metal based on workload control and isolation needs.

Choose provider-operated infrastructure

Choose provider-operated infrastructure

Choose provider-operated infrastructure

Review regions, GPU models, configurations, and prices across available infrastructure providers before deployment.

Review regions, GPU models, configurations, and prices across available infrastructure providers before deployment.

Choose provider-operated infrastructure

Review regions, GPU models, configurations, and prices across available infrastructure providers before deployment.

Plan spend with confidence

Plan spend with confidence

Plan spend with confidence

Plan spend with confidence

Work from visible hourly rates instead of combining variable compute, storage, and bandwidth charges.

Work from visible hourly rates instead of combining variable compute, storage, and bandwidth charges.

Built for GPU workloads that need control

Fluence is well suited for:

Host OpenClaw on always-on Virtual Servers for up to 85% less cost and connect it to external LLM APIs or routing layers. When you need self-hosted inference, you can also pair OpenClaw with Fluence GPU Cloud.

Production inference

Production inference

Production inference

Serve models with control over runtime configuration, networking, and transfer costs.

Recommended deployment:

GPU container or GPU VM

Model fine-tuning

Model fine-tuning

Model fine-tuning

Run adapters, checkpoints, and repeatable training cycles on persistent dedicated GPU capacity.

Recommended deployment:

GPU VM or GPU bare metal

LLM development

LLM development

LLM development

Test models, quantization methods, and serving frameworks in your preferred software environment.

Recommended deployment:

GPU container or GPU VM

Training pipelines

Training pipelines

Training pipelines

Run sustained single-node or multi-GPU jobs with control over software, storage, and configuration.

Recommended deployment:

GPU VM or GPU bare metal

Batch inference

Batch inference

Batch inference

Process documents, embeddings, media, and model outputs through repeatable GPU jobs.

Recommended Fluence deployment:

GPU container

Model research

Model research

Model research

Compare architectures, context settings, and precision formats in repeatable environments.

Recommended Fluence deployment:

GPU VM or GPU bare metal

Agent inference workloads

Agent inference workloads

Agent inference workloads

Host models and supporting services for AI agents while retaining infrastructure control.

Recommended Fluence deployment:

GPU container or GPU VM

Try Fluence with one GPU workload
Keep the evaluation focused. Move one representative workload from Vast.ai and compare total cost, reliability, and infrastructure control before changing the rest of your stack.

Host OpenClaw on always-on Virtual Servers for up to 85% less cost and connect it to external LLM APIs or routing layers. When you need self-hosted inference, you can also pair OpenClaw with Fluence GPU Cloud.

1

1

Choose a GPU model

Choose a GPU

model

2

2

Select container, VM, or bare metal

3

3

Pick an available provider and region

4

4

Launch a small test workload

5

5

Compare cost, setup experience, and infrastructure control

FAQ

FAQ

What is the main difference between Vast.ai and Fluence?

Can Fluence reduce GPU costs compared with Vast.ai?

Which GPUs are available on Vast.ai and Fluence?

Do both platforms support single-GPU and multi-GPU workloads?

How does infrastructure availability compare?

Show more

What is the main difference between Vast.ai and Fluence?

Can Fluence reduce GPU costs compared with Vast.ai?

Which GPUs are available on Vast.ai and Fluence?

Do both platforms support single-GPU and multi-GPU workloads?

How does infrastructure availability compare?

Show more

Plan GPU cloud costs with confidence

Compare GPU capacity across providers and deploy with control

over pricing, data transfer, and workload format.

Launch on-demand GPUs through Fluence Cloud or compare provider bids for reserved GPU capacity.